Supermicro Sells SambaNova Servers For Cheaper Chatbot Replies
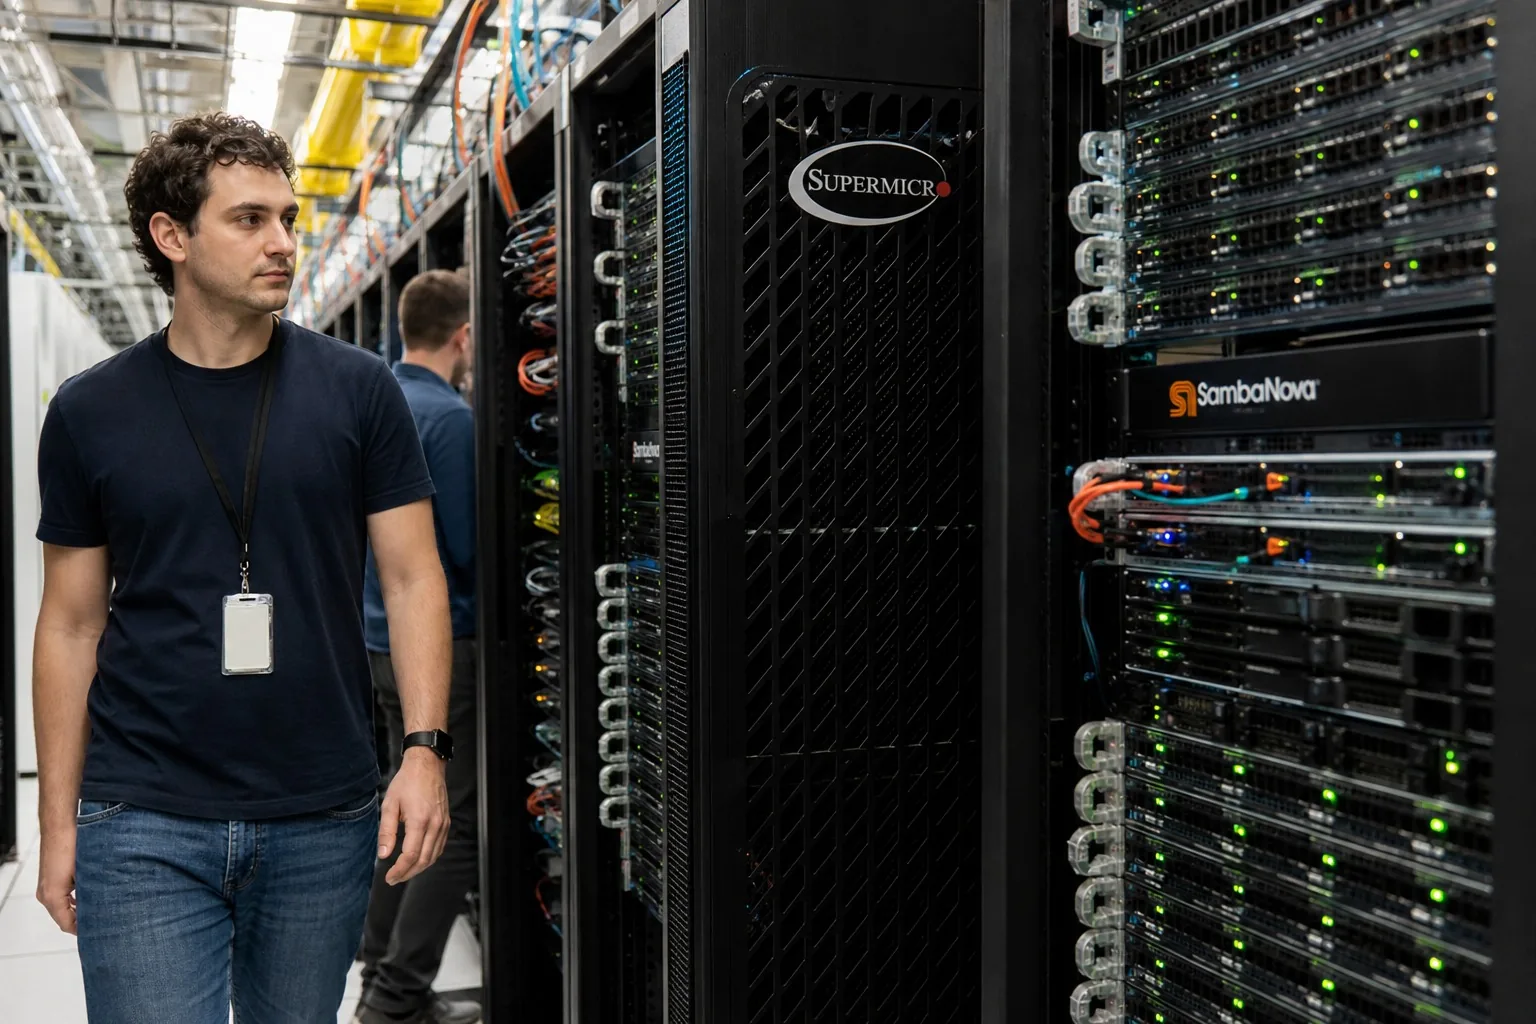
Supermicro will sell new server racks using SambaNova chips to help data centers run chatbot-style answers more cheaply alongside Nvidia GPU systems.
Key Takeaways
- SambaNova said its SN50 chips will power new inference racks built to run alongside Nvidia GPUs in data centers worldwide
- Supermicro will include the systems in its Data Center Building Block Solutions portfolio
- The racks are meant for high-performance inference, the stage where a trained model is used to answer prompts or run workloads in production
- Supermicro already serves customers that deploy multiple chip types inside one facility, easing trial deployments of SambaNova racks
SambaNova said the systems will become part of Supermicro’s Data Center Building Block Solutions portfolio. The same release said the racks are meant for high-performance inference, which is the stage where a trained model is used to answer prompts or run workloads in production.
Supermicro assembles servers and full rack-scale systems for cloud providers and enterprises.
SambaNova designs AI chips and systems software. Their deal matters because data centers are looking for more than one path to run inference as demand spreads beyond model training.
SN50 Racks Aim At The Inference Bottleneck
Training a model is the expensive process of teaching it from large datasets.
Inference is what happens after training, when the model serves live requests. That second phase is becoming a separate market because companies need lower-cost, highly available hardware for constant production use.
The new systems are designed for that market.
SambaNova said they will sit alongside Nvidia GPU deployments rather than replace them outright. That suggests buyers want mixed fleets, where one hardware class handles model training and another handles steady inference traffic.
This distinction has concrete operational implications.
Racks tuned for inference can be optimized for lower latency, lower sustained power draw and higher token throughput per watt than general-purpose training clusters. Operators choosing these systems will evaluate the effective cost per unit of inference (tokens or queries), the rack-level power envelope and how many cabinets are needed to meet peak capacity without overprovisioning GPU training clusters.
Also Read: Drax Power Station Could Become A £20bn AI Data Center Hub
From GPU Scarcity To Mixed-Fleet Design
The backdrop is a two-year scramble by cloud providers and enterprises to secure enough AI hardware.
Early demand centered on Nvidia training clusters because frontier models needed the broadest software ecosystem and the most proven scaling path.
As workloads matured, buyers started splitting the stack. Training still leans on top-end GPUs.
Inference opens room for custom silicon, application-specific accelerators and rack-level designs that can target known model sizes and traffic patterns.
That is where SambaNova’s offering enters. Supermicro already serves customers that deploy multiple chip types inside one facility.
Adding SambaNova into that catalog gives buyers another option without forcing them to rebuild the entire software and operations layer in one step.
Distribution And Switching Risk
Distribution is often harder than chip design. Many AI hardware startups can build silicon.
Far fewer can get their systems into standard enterprise purchasing channels.
Supermicro helps close that gap because it already sells integrated racks into the customers SambaNova wants, from enterprises to service providers. If those buyers can order the product through a familiar systems vendor, trial deployments become easier.
The existence of a commercial channel through Supermicro indicates a shift from prototype to volume availability, which in practice reveals more about likely capacity and supply than a vendor’s product roadmap alone.
The wording around operating alongside Nvidia GPUs also reduces switching risk. A data center can add SambaNova capacity for inference without ripping out existing GPU clusters or rewriting every workflow at once.
Practically, that means operators can balance capital expenditure across specialized racks, buying Supermicro-SambaNova inference capacity to hit cost-per-query targets while leaving GPU investment focused on training and multipurpose workloads.
SambaNova and Supermicro’s pitch is that SN50 racks let operators map specific inference workloads to hardware optimized for those patterns. For example, an e-commerce search service that requires consistent low-latency throughput can be placed on SN50 racks sized to meet peak token rates within a defined power budget, while episodic large-batch training stays on GPU clusters.
The main metrics for buyers will be published throughput, measured in queries or tokens per second, rack-level power draw, and cost per unit of inference.
Capital commitments and product availability seen in the market will be stronger signs of deployment intent than promotional claims.
For cloud and enterprise buyers, the next thing to watch is whether SambaNova publishes throughput, power and cost numbers for these systems against GPU-based inference options. Without those figures, the deal is mainly an access story.
With them, it becomes a head-to-head pricing and capacity comparison.
Read Next: RLVR Training Makes Chatbots Guess On Harder Problems