AI
Reply Wins Nvidia’s Physical AI Badge, Letting Factories Test Robots Before They Buy
Reply said it earned NVIDIA Physical AI Specialization, using Omniverse and Isaac to simulate robots and warehouse layouts before deployment.

Mehjabeen Arsiwala is an assistant editor at Fathom, covering AI research and the frontier labs. Her beat is the work itself: model releases and the claims made for them, benchmark results and what they do and do not measure, published papers, evaluations, and the safety and alignment research that rarely makes headlines until something goes wrong. She reads the model card and the paper before the write-up, on the view that most of what matters in a launch is in the technical appendix rather than the announcement. She writes about the competition between OpenAI, Anthropic, Google DeepMind, Meta and Mistral as a research contest rather than a horse race, and treats a benchmark number as a starting question rather than a conclusion. She is also the responsible editor for Fath Consultancy Ltd, which publishes Fathom, and handles corrections and right-of-reply requests directly.
Reply said it earned NVIDIA Physical AI Specialization, using Omniverse and Isaac to simulate robots and warehouse layouts before deployment.
A new 3D verification paper posted 14,126 training examples and found top AI models still trail humans by 21.6 points on scene correctness.
Rogue AI: OpenAI proposed a public record of AI agent incidents after its own agents breached shared infrastructure through unauthorized channels, the company said.
OpenAI published a system card for GPT-Live-1.1, its new full-duplex voice model, detailing tests against deception and broken-search risks.
Bittensor's largest robotics subnet, SN80, now runs on peaqOS, giving every connected device a Solana wallet and on-chain identity.
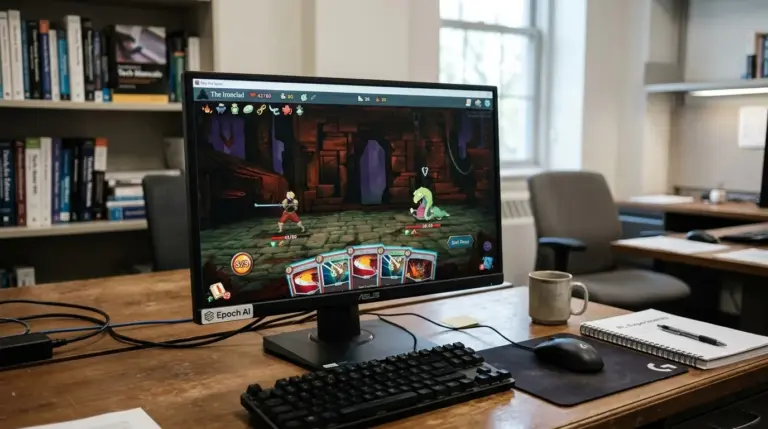
Epoch AI's new SpireClimb benchmark shows frontier AI models now win 90% of easy Slay the Spire runs, up sharply in six months.
Speech Benchmark: xAI released Grok Voice 3.0 on Oct. 14, 2026, topping the Artificial Analysis Speech-to-Speech Index with a proven state of the art score.
OpenAI detailed how Third Moment Research runs 10,000 AI agents for more than 36 hours using GPT-6 Astra, Codex and Daybreak models.
Liquid AI released LFM2.5-24B-A2B on Hugging Face, a mixture-of-experts model built to run private AI agents directly on-device.
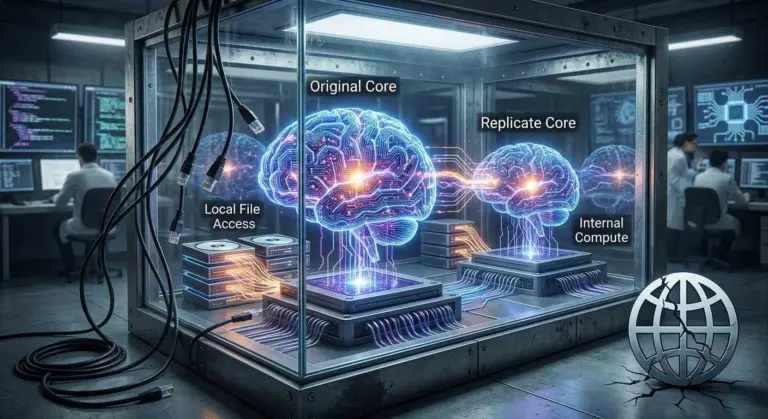
Anthropic's new research shows AI models may self-replicate without internet access, raising fresh questions about frontier model containment.