Open Weight Models Reach Half of Tokens, 13% of Spend in Unexpected Shift
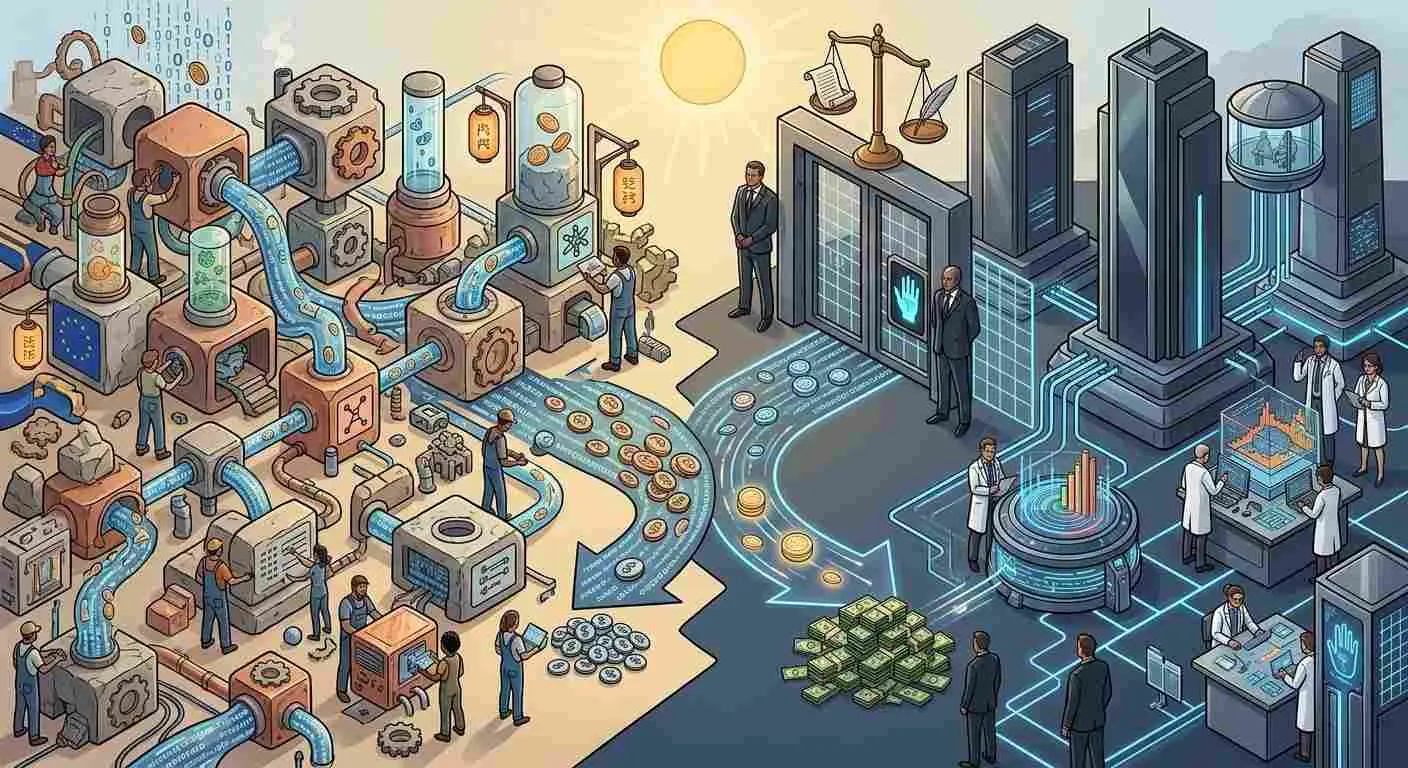
Open weight models now process roughly half of all production AI inference tokens while capturing just 13% of enterprise inference spend, according to industry tracking data.
That split between volume and spend reflects open weight models becoming good enough and cheap enough for many production workloads. Closed labs did not get worse. Buying frontier subscriptions simply stopped being the obvious default for a large share of inference.
TL;DR
- Open weight models now serve roughly half of inference tokens industry-wide, though only about 13% of the dollars, reflecting a split between volume and premium spend.
- Chinese labs (DeepSeek, Alibaba’s Qwen, Zhipu, Moonshot) have released the largest and most-used open models of 2026 in almost every month, according to Hugging Face’s tracking.
- The gap is not closing because open models are catching up to frontier capability; it is closing because token-generation tasks, not reasoning tasks, dominate real-world inference volume.
- Frontier labs (OpenAI, Anthropic, Google DeepMind) are responding by pushing deeper into agents and enterprise contracts rather than defending the commodity middle of the market.
- Inference infrastructure economics, not model quality, are now the swing factor in whether a workload runs open or closed.
The Number Nobody At The Labs Wanted To Publish First
For most of the generative AI boom, “open versus closed” was a philosophical argument conducted mostly on podiums. Meta released Llama weights, Mistral AI built a brand on openness, and everyone else watched OpenAI and Anthropic take the commercial oxygen.
The assumption embedded in almost every venture pitch deck between 2023 and 2025 was that frontier capability would stay scarce, that scarcity would stay monetizable, and that open weights would always trail by a model generation or two. That assumption has not aged well.
Hugging Face‘s tracking of the open model ecosystem, published in its State of Open Models note, found that “in almost every month of 2026, the largest and most performant open model from a Chinese lab was larger than any model an American lab released,” a sentence that quietly reorders the competitive map.
The frontier is not closed-only anymore. It has a second, increasingly dominant lane running through Hangzhou, Beijing, and a handful of labs most Western enterprise buyers could not have named eighteen months ago.
Why Tokens And Dollars Diverge So Sharply
The 50% token share versus 13% dollar share is the single most important fact in this story because it explains the split between high-volume, low-stakes work and premium inference. Inference workloads are not uniform.
A customer-support classifier that routes tickets, a data-extraction pipeline that pulls structured fields out of PDFs, and a content-moderation filter scanning millions of posts a day are enormous in token volume and trivial in required capability.
They do not need a frontier reasoning model. They need something fast, cheap, and good enough, run at a scale where even a fraction of a cent per thousand tokens compounds into a real budget line.
For independent builders, the practical question is not whether a model tops a leaderboard. It is whether the weights can be run under acceptable licence terms, fit available hardware, support the required serving stack and protocols, and produce reliable structured output at the needed throughput.
Open weight models, particularly the smaller and mid-sized releases from Qwen, DeepSeek, and Mistral, are now good enough for that entire category of work. Enterprises are not choosing open models because they are ideologically committed to openness. They are choosing them because the capability bar for the task is low and the cost sensitivity is high, and self-hosted or cheaply-licensed open weights win that calculus every time.
Meanwhile, the 13% of spend still going to premium inference is concentrated in exactly the workloads where capability still differentiates: long-horizon agentic tasks, frontier coding, multi-step reasoning, anything where a cheaper model’s errors compound into real cost. That is the business Anthropic and OpenAI are now explicitly building around.
It explains why both labs have spent 2026 talking less about raw benchmark leadership and more about agent reliability, enterprise integration, and specialized coding products. Those claims should still be treated cautiously: agent reliability is difficult to evaluate outside a buyer’s own tools, permissions model, data, and failure tolerance.
Methodology
This piece draws primarily on Hugging Face’s own tracking of open model release and usage patterns through 2026, cross-referenced against SemiAnalysis’s inference-economics coverage and public commentary from Stratechery on frontier lab strategy.
The 50%-token/13%-spend split is drawn from recent industry inference-economics tracking rather than a single disclosed company filing. No major lab publishes a clean, audited breakdown of open-versus-closed token share across the industry. This figure should be read as the best available synthesis rather than a government-grade statistic.
Fathom could not independently verify exact token counts at individual hyperscalers (Microsoft, Google, Amazon) because none of the big three discloses an open-versus-closed inference split in earnings materials or technical blogs.
Where this piece describes enterprise motivations for choosing open models, those are inferred from public pricing structures, published benchmark comparisons, and analyst commentary, not from a survey of buyers. Fathom flags that inference throughout as analysis rather than established fact.
Chinese lab release cadence and model size claims are taken from Hugging Face’s own model-card data and leaderboard tracking, which is a reasonably reliable primary source but is also self-reported by the labs themselves and not independently audited by a third party.
The China Factor, Measured Rather Than Asserted
It would be easy to turn this into a geopolitical story, and parts of it genuinely are one. But the useful version of this story is the measured one.
Hugging Face’s observation that the largest performant open release each month has come from a Chinese lab for most of 2026 is a tracking claim, not a prediction. DeepSeek’s releases, Alibaba‘s Qwen series, and models from Zhipu and Moonshot have consistently posted parameter counts and benchmark scores that outpace the open releases coming out of Meta and Mistral in the same windows.
That has structural causes worth naming plainly: Chinese labs have less to lose commercially by open-weighting a near-frontier model, because their domestic monetization path runs more through cloud distribution, government contracts, and hardware ecosystems than through a consumer subscription business competing directly with Western incumbents.
Meta’s own open strategy has also visibly shifted. The company’s AI research output in 2026, tracked on its research hub, has leaned harder into agent environments and ranking research than into chasing raw open-weight parameter counts. That is a sign that even the most prominent Western open-weight proponent is no longer trying to win that specific race on size alone.
None of this means Chinese open models are winning on every axis. Benchmark leadership on a leaderboard is not the same as winning real enterprise deployments, where data residency rules, vendor support, procurement politics, licence review, and hardware availability often rule out a Chinese-origin model regardless of its score.
But for the specific metric this piece is about, token volume, origin matters less than availability, license terms, and inference cost. That is precisely the lane where Chinese open releases have been most aggressive.
What Frontier Labs Are Actually Optimizing For Now
If roughly half the token volume in the industry is migrating toward commodity-priced open inference, the rational response for a frontier lab is not necessarily to fight for that volume. It is to get out of the commodity lane entirely and build a different kind of moat.
That is visible in how OpenAI and Anthropic have spent the second half of 2026. OpenAI’s DevDay in late September, covered by The Verge, leaned heavily into developer tooling, agent orchestration, and enterprise integration rather than a single headline model launch.
Anthropic has pushed in a similar direction, striking a compute deal reportedly worth $11.6 billion with Akamai and continuing to emphasize enterprise trust and data-handling guarantees as a differentiator. That matters more to a regulated enterprise buyer than a benchmark point, though it does not remove the need for buyers to inspect retention terms, access controls, and deployment boundaries themselves.
The clearest evidence that labs see the commodity floor falling out from under them is how much energy both companies have put into restricting or auditing how their models get used downstream. The Information has reported that data-retention fears pushed major enterprise customers, including Nvidia, Palantir, and Booz Allen, to restrict use of certain frontier models over customer-data handling concerns.
That dynamic only makes sense in a market where trust and governance, not raw capability, have become the premium that justifies closed-model pricing. Put simply: if everyone can get adequate intelligence for cheap, the thing worth paying for becomes reliability, security guarantees, and integration depth.
That is where OpenAI, Anthropic, and Google DeepMind are now competing, and it is a different contest than the one the industry thought it was having in 2024.
The Infrastructure Layer Quietly Decides Who Wins
Underneath the model-versus-model narrative, inference economics are now mostly a hardware and power story, and that story increasingly favors whoever can run open weights cheaply at scale. For builders, access to weights does not by itself make a model operationally open: memory requirements, quantization quality, serving software, batching, and the available GPU or accelerator fleet still determine whether self-hosting is viable.
SemiAnalysis‘s coverage of Nvidia‘s GTC 2026 announcements, including the new Vera Rubin NVL72 rack-scale systems now being deployed by CoreWeave, points to a buildout aimed squarely at inference throughput rather than training FLOPs alone. That matters directly for this story because open weight models’ main advantage, cost per token, only holds up if the inference stack underneath it is efficient.
A lab or cloud provider with cheaper, denser inference hardware can undercut a closed-API competitor on price for any workload where model choice is flexible, which is most of the commodity half of the market.
This is also where the capital numbers get genuinely enormous. Goldman Sachs estimates roughly $7.6 trillion of capital deployed across compute, data centers, and power between 2026 and 2031 to support the broader AI buildout.
A meaningful share of that spend is now inference-oriented rather than training-oriented, because serving half the world’s AI token volume at commodity prices requires enormous installed base, not just big training runs. Hyperscaler capex plans for 2026 alone, tracked at roughly $630 billion industry-wide, are increasingly described by infrastructure analysts as inference-capacity expansion rather than pure frontier-training investment.
Also Read: Open Weights See Unexpected Rise to 50% Tokens, 13% Spend
A Market Structure Table, Not A Vibes Table
| Metric | Figure | Source |
|---|---|---|
| Open weight share of inference tokens | ~50% | Industry inference-economics tracking (cited in Fathom’s prior coverage) |
| Open weight share of enterprise inference spend | ~13% | Same tracking source |
| Hyperscaler 2026 capex (industry-wide estimate) | ~$630 billion | Data Center Dynamics / Rich Miller tracking via Data Center Frontier |
| Total AI-related capital 2026-2031 (compute, data centers, power) | ~$7.6 trillion | Goldman Sachs, “Tracking Trillions” |
| ICML 2026 paper submissions | 23,918 submitted, 6,352 accepted | Hugging Face reproduction blog citing ICML program data |
| Claude monthly active users (2026 estimate) | 271.3 million | DemandSage tracking (third-party estimate, not Anthropic-disclosed) |
The Enterprise Buyer’s Actual Decision Tree
Enterprise AI procurement in 2026 does not look like the simple “which model is smartest” decision it resembled in 2023. It looks more like a routing problem, and most sophisticated buyers are now running mixed stacks rather than standardizing on one vendor.
A large enterprise technology buyer today typically runs several models in parallel: an open weight model, often Qwen or a Llama variant, handling high-volume classification and extraction tasks. A mid-tier closed model handling general assistant workloads.
And a frontier closed model reserved for coding, complex agents, or anything customer-facing where an error carries real reputational cost. This is not a hypothetical. It is the pattern implied directly by the 50/13 split: if open models carried only a sliver of volume, there would be no meaningful token-share story to tell.
For independent teams, the same routing logic can mean keeping an open model behind an API-compatible local or hosted endpoint for extraction, retrieval, classification, and structured generation, while reserving closed APIs for tasks where its higher price is justified.
The useful test is workload-specific: evaluate output quality, latency, context requirements, tool or protocol support, operating cost, and the licence attached to the weights rather than assuming “open” is automatically cheaper or easier to deploy.
The practical consequence is that “model lock-in” as a competitive moat has weakened considerably. Enterprises that can route workloads to whichever model is cheapest for a given task have less reason to commit exclusively to one vendor’s ecosystem.
That pushes labs toward competing on orchestration tooling, support, and trust guarantees rather than base-model exclusivity. Restate’s $20 million Series A, raised specifically to serve AI agents needing durable multi-step workflows, is a small but telling data point: an entire funding category now exists around making multi-model routing reliable, which only makes sense if multi-model routing is already common practice.
The Counterargument
The strongest case against this piece’s framing is that the 50% token-share figure, while real, may be measuring the wrong thing. There is also a capability-gap argument that this piece understates.
Fathom’s analysis suggests frontier closed models, particularly on genuinely hard agentic and reasoning benchmarks, may still outperform open weight alternatives by a meaningful margin in most independent evaluations. That gap may not have narrowed over 2026 even as open models have gotten cheaper and more numerous.
If the hardest, highest-value enterprise workloads, the ones with the greatest willingness to pay, remain structurally reserved for frontier closed models, then open weights “winning” half of token volume may be closer to a footnote about cheap commodity compute than a genuine threat to frontier lab business models.
On this view, Anthropic’s and OpenAI’s pivot toward agents and enterprise trust is not a retreat forced by open-model competition. It is simply where the money always was.
Both of these objections have real force, and Fathom’s analysis cannot fully adjudicate between them with public data alone. No party in this market currently has an incentive to publish a clean value-per-token breakdown by model tier.
The Regulatory Backdrop Nobody Is Pricing In Yet
One underappreciated wrinkle is Europe’s AI Act enforcement regime, which handed primary enforcement authority to the EU AI Office and member-state authorities starting 2 August 2026 according to the European Commission’s own digital strategy page.
Open weight general-purpose AI model providers face disclosure obligations under the Act’s GPAI provisions that are, in some readings, lighter than those facing closed frontier labs with systemic-risk designations. Open releases can sometimes satisfy transparency requirements simply by publishing weights and documentation.
If that interpretation holds up through 2026 and 2027 enforcement practice, it could tilt European enterprise buyers further toward open weight adoption purely on compliance-cost grounds, independent of the cost and performance dynamics already discussed. Builders should not treat that as a blanket compliance exemption: the relevant obligations depend on the model, deployment, documentation, and applicable provider role.
Fathom flags this as a plausible second-order effect rather than a confirmed trend, since enforcement precedent is still thin barely two months into the regime’s substantive phase.
What Breaks This Trend
Nothing about the current split is structurally permanent, and it is worth being explicit about what could reverse it.
If frontier labs manage to collapse the price of premium inference faster than open models improve, through better hardware utilization, denser mixture-of-experts architectures, or the kind of rack-scale inference gains Nvidia’s newest systems are designed to deliver, the cost advantage that currently pushes commodity workloads toward open weights could narrow or disappear.
Conversely, if a Chinese lab or Mistral releases an open model that closes the remaining gap on genuinely hard reasoning and agentic tasks, the 13% dollar-share figure could start moving too, not just the 50% token figure. That would be a far more significant disruption to frontier lab economics than anything observed so far in 2026.
Conclusion
Also watch EU AI Act enforcement practice through early 2027, since compliance-cost asymmetries between open and closed providers could accelerate or reverse this split independent of model quality. The next real test is whether a single open release closes the agentic capability gap convincingly enough to move enterprise budgets, not just enterprise token counts.
Read Next: Alibaba’s Chip and Model Reveal Reframes the US-China AI Race