AI
Agent Memory Overtakes Full Context With 16 Tokens In Real FactKG Test
agent memory. A new LLM memory paper shared on X says 16 learned memory tokens beat full-context inference on FactKG, pointing to cheaper agent recall.

Bibhu Pattnaik is a senior writer at Fathom, covering AI infrastructure. His beat runs from silicon to substation: chips and the companies making them, foundry capacity and supply constraints, data centre construction, memory, interconnects, and the electricity that increasingly determines where and whether AI capacity can be built at all. He follows Nvidia, AMD, Intel, TSMC and Broadcom as the physical layer beneath every model announcement, and treats inference cost as the number that decides which AI products are viable businesses. He is interested in bottlenecks, because the constraint moves and whatever is scarce this year explains most of the industry's behaviour next year. Where a company's capital expenditure and its public strategy disagree, he tends to believe the capital expenditure.
agent memory. A new LLM memory paper shared on X says 16 learned memory tokens beat full-context inference on FactKG, pointing to cheaper agent recall.
A Tencent research paper describes coding agents that refine their own training loop, a step toward recursive self-improvement in AI systems.
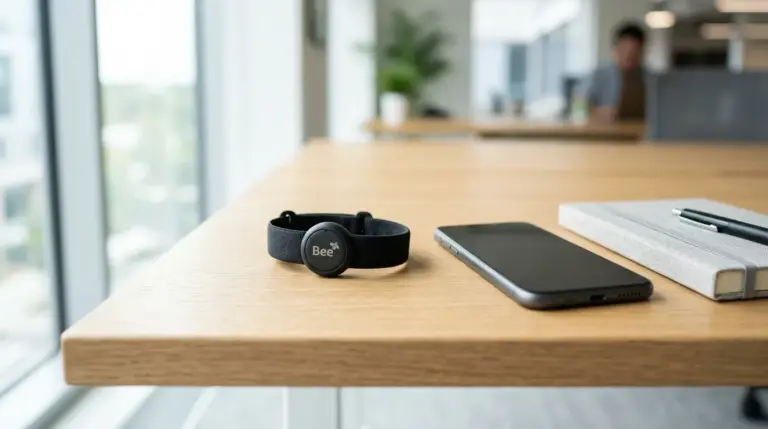
Amazon launched two AI wearables built on its Bee acquisition, devices that record and analyze a person's day, Bloomberg's Mark Gurman said Thursday.
Salience Labs raised $125 million in Series B funding, backed by Intel Capital and AMD Ventures, to scale photonic chips for AI datacenters.
AI chip design: Nvidia and ChipAgents launched Build-A-Chip-Bench Oct. 14, a benchmark testing AI agents across the full chip design flow from spec to layout.
UK sovereign cloud: Starling Bank is building a transactional AI model with Nvidia, training it on UK cloud provider Civo to cut reliance on US cloud giants.
AI Agent: Artificial Analysis added AMD's MI355X chip to its AA-AgentPerf index on Oct. 14, 2026, putting it in direct comparison against Nvidia hardware.
Inworld launched a realtime inference API serving Gemma 4, GLM, DeepSeek and MiMo for consumer AI apps, built on an OpenAI-compatible interface.
EntroPack Lets: GPU memory compression: ModelScope released EntroPack, a PyTorch library letting developers tune AI model weight storage to fit tighter GPU memory budgets.
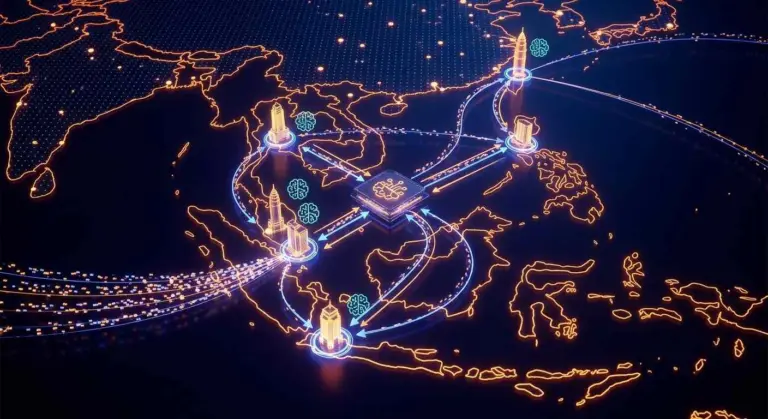
AWS adds global cross-Region inference for OpenAI's GPT models on Amazon Bedrock, giving Thailand, Malaysia, Singapore, Indonesia and Taiwan faster access.