Amazon Lets Labs Fold Private Proteins Without Leaving Their Own Cloud
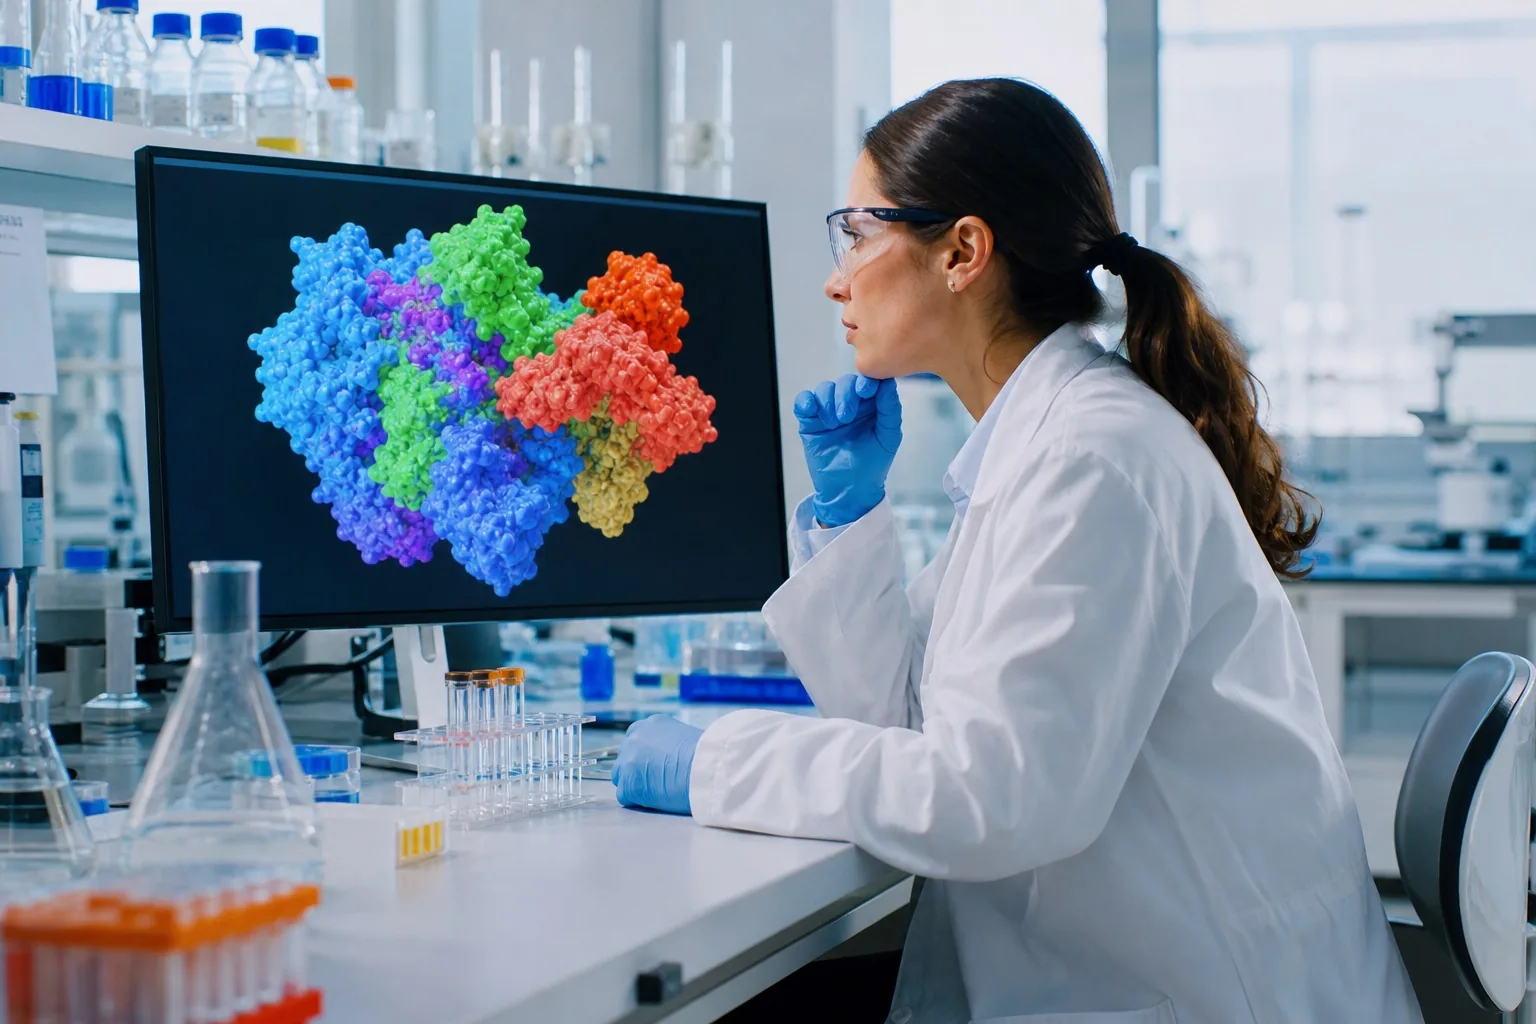
Amazon Web Services now lets labs run OpenFold3, an open source AI model that predicts the 3D shapes of proteins and the drugs that bind to them, on servers inside their own AWS accounts.
Key Takeaways
- OpenFold3-preview is now on Amazon SageMaker JumpStart, the AWS catalog of ready-to-run models
- The model predicts the 3D structure of proteins, DNA, RNA and small drug molecules from their sequences
- Each prediction runs on one GPU, and a four-GPU machine can run four predictions at once
- Adding a sequence alignment lifted a test complex’s average confidence score from 30 to 98
AWS said in a Nov. 13 post that the endpoint runs with network isolation, which can help keep sequences within a customer’s own account. The model comes from the OpenFold Consortium and the AlQuraishi Lab at Columbia University, which call it a “research preview” and publish its code and weights under the Apache 2.0 license.
Also Read: Anthropic Says Claude Helped Map Bacterial Shell In 3D
Why Labs Want This
AWS says teams often struggle to run folding models on their own. They need GPUs, a working software stack, large model files and a server that can handle requests that take minutes.
JumpStart packages OpenFold3 in a container AWS maintains, on a managed endpoint that queues requests and warms up the GPUs. Real-time endpoints cut off responses at 60 seconds, so AWS points labs to asynchronous endpoints, which allow up to an hour per request. Requests and results pass through Amazon S3. A test complex took about 1.5 minutes per prediction.
The Alignment Makes Or Breaks It
The endpoint does not call outside alignment servers. Labs bring their own precomputed multiple sequence alignments, which are lists of related sequences that help the model. AWS warns that the default ColabFold command sends sequences to a public server, so labs with private data should run that search on their own databases.
The gap was huge in an AWS test on the enzyme carbonic anhydrase II with zinc and the drug acetazolamide.
AWS cautions that this complex is well studied and likely in the model’s training data, so the test shows the workflow rather than how the model does on new targets.
What It Costs To Run
Endpoints bill per instance-hour while running, idle time included. The default machine, ml.g6.4xlarge, has one GPU. The ml.g6.12xlarge has four. For larger proteins, the cost per prediction on the four-GPU machine was close to the one-GPU machine, AWS said.
Endpoints can also scale down to zero when no work is waiting. In AWS tests that took about 15 to 20 minutes after the queue emptied, and the first request after a restart runs slower.
Read Next: Amazon Adds Nvidia Chip Sharing To Cut AI Serving Costs