Kazakhstan Telecom Giant Fires Up 880 Nvidia Chips To Build Local AI
Kazakhtelecom, Kazakhstan’s biggest phone and internet company, has switched on 880 Nvidia AI chips in data centers in Astana and Almaty to build AI that speaks Kazakh and to power local robotics tests.
Key Takeaways
- Kazakhtelecom deployed 400 NVIDIA H200 and 480 B300 GPUs in Astana and Almaty, adding 880 accelerators to support national AI projects
- The hardware sits with Kazakhtelecom and local research hubs to train Kazakh-language models and run low-latency inference for robotics pilots
- NVIDIA Kazakhstan chose 400 H200s for training and 480 B300s for inference at scale
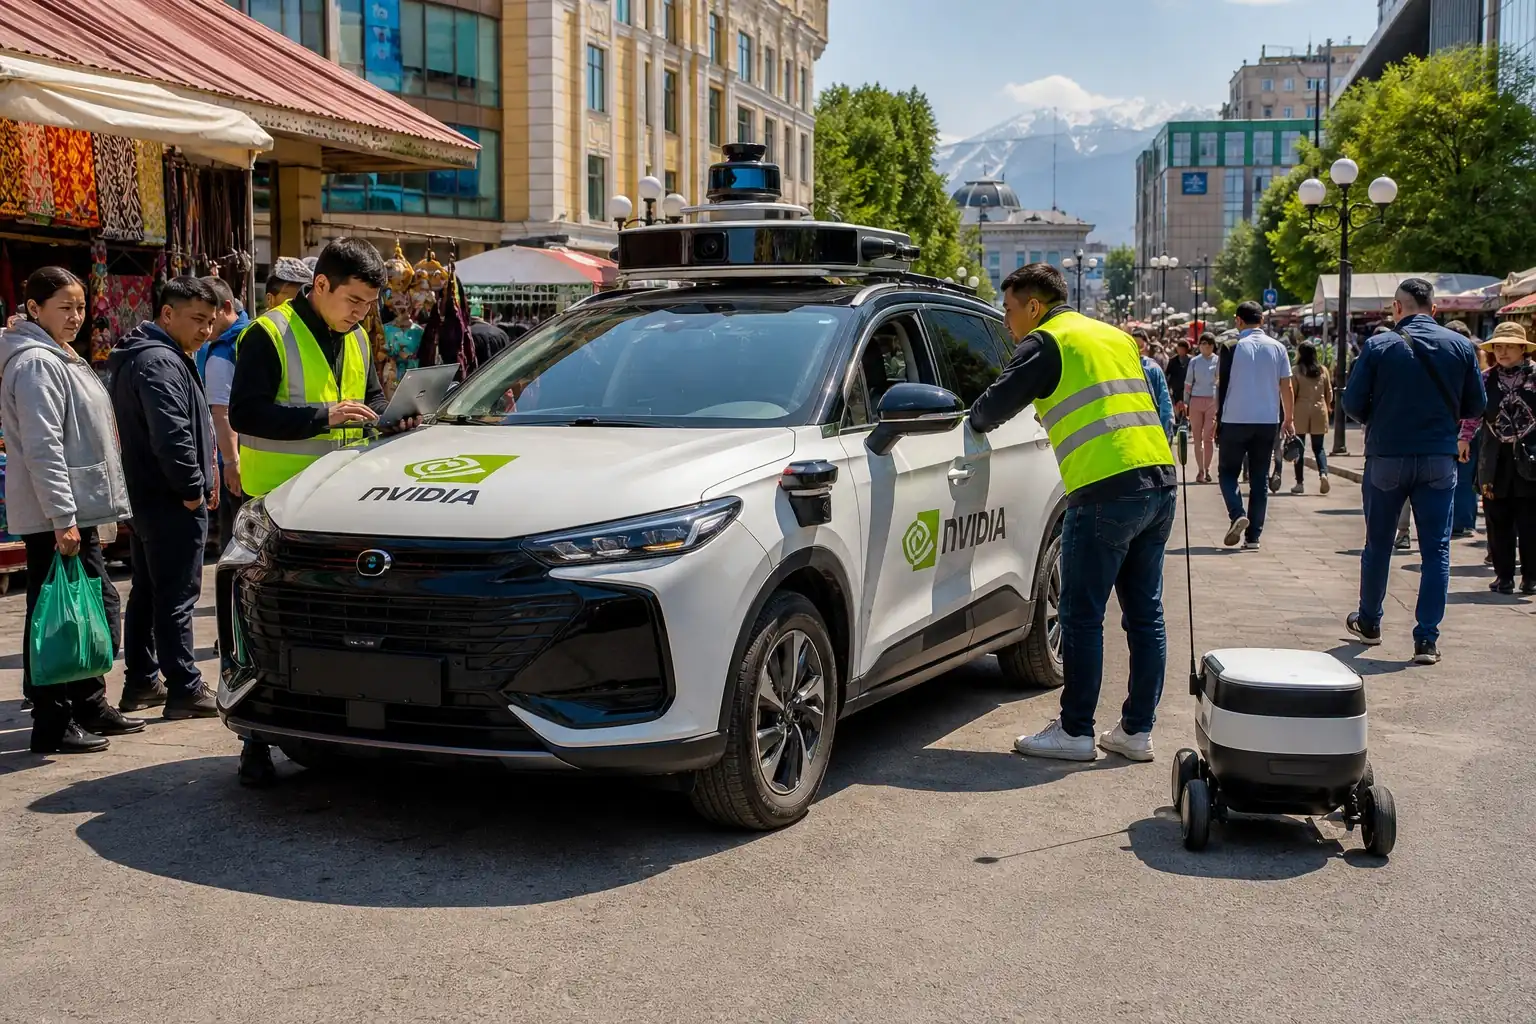
- inDrive and Pony.ai will explore autonomous mobility built on NVIDIA Hyperion in Kazakhstan, linking accelerators to vehicle stacks and edge inference pilots
The company said the hardware sits with Kazakhtelecom and local research hubs to train Kazakh-language models and run low-latency inference for robotics pilots, naming H200 and B300 as the installed models and tying the work to Jensen Huang‘s public meetings in Astana.
It further said inDrive and Pony.ai will explore autonomous mobility built on NVIDIA Hyperion in Kazakhstan, showing how the accelerators will link to vehicle stacks and edge inference pilots.
How NVIDIA Kazakhstan Mixed Hardware For Training And Inference, Kazakhstan AI
NVIDIA Kazakhstan chose 400 H200s for training and 480 B300s for inference at scale. The H200 is optimized for high-memory model training and large-batch workloads, while the B300 is designed for dense, low-latency inference.
This hardware split lets teams iterate models on H200 clusters and then deploy trimmed, efficient versions to B300 racks near robots and vehicles. NVIDIA Kazakhstan framed the architecture as a national pipeline that keeps data and model tuning local, which reduces cross-border transfer costs and latency for physical AI use cases, and the company highlighted energy-abundant regions and co-located partner facilities as enablers of sustained compute capacity.
Also Read: OpenAI Locks Down AI Training As Stolen Models Cost Near Zero To Copy
From Jensen Huang’s Visit To Rack-Level Deliveries
NVIDIA Kazakhstan follows Jensen Huang’s Astana visit and a public fireside chat with Deputy Prime Minister Zhaslan Madiyev about building an “AI nation.” The company said the project aims to produce models that understand Kazakh language and cultural context and to apply AI across agriculture, mining and transport.
The partner announcement with inDrive and Pony.ai links the compute builds to planned mobility pilots. This deployment continues a trend of labs and vendors placing onshore accelerated compute to run national-language models and physical AI systems, reducing dependence on distant cloud regions for latency-sensitive workloads.
Also Read: AI Chip Startup Infinity Grabs Meta Talent To Challenge Nvidia
What This Change Means Practically For Local Teams
NVIDIA Kazakhstan gives Kazakh teams near-lab scale compute parity for early model development and real-world inference testing.
Local researchers get faster iteration on language and robotics models, and operators can run inference close to sensors and vehicles to meet strict latency windows. Talent and data governance remain constraining factors, and the presence of accelerators does not guarantee production-grade model releases or open checkpoints.
The public material specifies hardware types and counts but stops short of critical operational details that determine what independent teams can actually run. The announcements do not specify license terms for any models or tooling, nor do they publish model weights or checkpoints.
Without explicit licensing and published weights, third-party builders cannot reproduce or legally redistribute trained models.
The posts also omit concrete compute-to-train estimates (GPU×hours, memory footprints, or batch-size targets) and do not state whether common ML protocols and orchestration stacks (for example, Triton, ONNX, Horovod, or standard Kubernetes/GPU operator setups) will be supported on the deployed racks.
Those are practical requirements for porting community or open-source training and inference workloads to the site, and their absence limits independent teams’ ability to plan cost, time, and engineering effort.
What to watch next are published model checkpoints or benchmark results from Kazakh research groups, the scope and timing of inDrive and Pony.ai’s robotaxi trials, and any regulatory choices about data residency that follow the compute build. If teams publish models, disclose license terms, or start public pilot routes, the practical impact of these 880 GPUs will become measurable.
Read Next: Cohere Hides Patient And Bank Data From Outsiders On Azure