Supermicro Hands Companies A Memory Saver For Thousands Of Chats
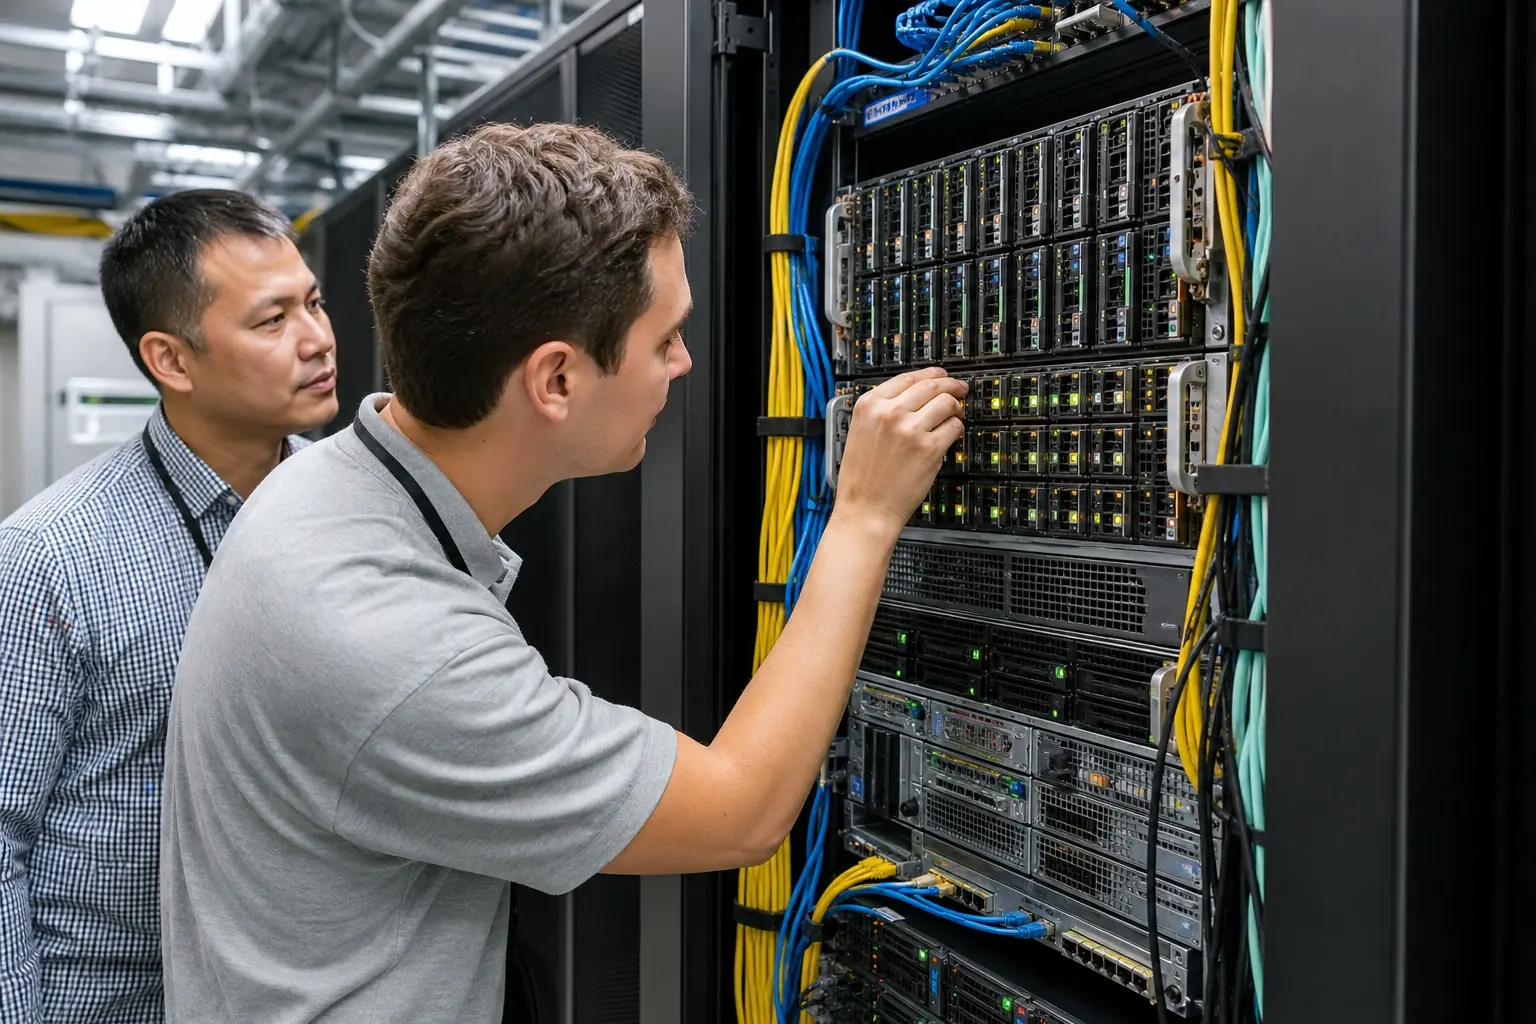
Supermicro IBM Nvidia introduced a rack- and server-level system that integrates KV cache handling into hardware and deployment architecture to reduce GPU memory pressure and speed long-context AI inference
Key Takeaways
- Supermicro introduced a system with IBM and Nvidia to ease GPU memory pressure during long or repeated prompts
- KV cache stands for key-value cache that stores parts of a model’s prior attention calculations to avoid recomputation for every token
- Supermicro pitched a rack- and server-level product that integrates KV cache handling into hardware and deployment architecture
- The Supermicro release and Nvidia blog do not disclose availability dates, pricing, per-query rate limits, or which regions will include integrated KV cache
Supermicro introduced a system with IBM and Nvidia to ease GPU memory pressure during long or repeated prompts, affecting models that handle thousands of tokens.
Supermicro said the system combines its infrastructure with IBM software and Nvidia acceleration to improve inference performance, and Nvidia’s blog says agent workloads now bounce between GPU reasoning and CPU execution, which raises the value of smarter memory handling.
KV Cache Targets The Expensive Part Of AI
KV cache stands for key-value cache, a memory layer that stores parts of a model’s prior attention calculations so the model does not recompute them for every token.
In plain terms, it lets a model remember the heavy math from the start of a conversation.
That matters most for chatbots, coding agents and retrieval systems with long contexts because repeated tokens otherwise force recalculations that consume GPU memory and time. Supermicro is pitching a rack- and server-level product that integrates KV cache handling into hardware and deployment architecture so buyers can rely on pre-integrated memory reuse rather than building the feature themselves.
Also Read: Hidden AI Server Hacks Can Survive Reinstalls As Nvidia Fights Back
From Research Tweak To Rack-Level Product
Supermicro, which builds server and rack systems, is responding by packaging memory efficiency into hardware and deployment architecture.
IBM’s part matters because enterprise buyers often want software orchestration and support layers, not just a box of GPUs. The offering pairs Supermicro hardware with IBM software and Nvidia acceleration to make KV cache an operational feature, not just a lab optimization.
How The KV Cache Changes Buyer Math
The KV cache is valuable when many enterprise prompts share structure, for example, a legal review tool using the same system prompt and policy context across thousands of sessions.
If that shared context stays cached, systems avoid recalculating it, reducing latency and improving throughput on fixed hardware. For companies running customer support or code agents, those savings compound across large volumes of calls.
Compared with older inference tuning, the KV cache affects both speed and capacity.
The next technical test is whether vendors can keep the cache coherent across distributed systems, which becomes harder when sessions move between machines or between GPU and CPU memory.
The Next Fight Is Inference Margins
This release also shows where AI infrastructure competition is moving. Buyers now measure how many useful responses each server can deliver per dollar and whether that performance holds at scale.
On availability and economics, the announcement demonstrates architectural potential but leaves practical details unclear.
Supermicro’s release and Nvidia blog do not disclose general availability dates, pricing, per-query rate limits, or which regions and product tiers will include the integrated KV cache. That gap matters because a launch demo shows possible peak performance under controlled conditions.
Customers need concrete service tiers, sustained throughput numbers and pricing to judge day-to-day value.
Supermicro’s challenge is that the KV cache technique is recognized rather than proprietary. The vendor’s commercial win depends on customers deciding it is easier and more reliable to buy the optimization pre-integrated than to build and operate it themselves.,
Read Next: Anthropic’s Claude Code Has Been Sending Users’ Email Addresses To Websites