AI Agents Burn More Cash The Longer They Work For You
Tech companies are pushing AI agents that can do tasks step by step, but the more work they do, the more they can cost, slow down, and go wrong.
TL;DR
- AI agents are AI systems that do multi-step work by combining a language model with memory, tools, and a way to act in an environment.
- A normal chatbot usually answers once, while an agent can plan, take actions, inspect results, and revise its next step.
- Agents can save time on messy tasks, but they add cost, delay, and new failure points that simple prompts do not have.
What AI Agents Actually Are
People often talk past each other when they say “agent.” Some mean a fully autonomous system that can work with little supervision. Others mean a simpler setup that still needs a person to start each task. Anthropic said the term can describe anything from tightly controlled workflows to more open systems that direct their own tool use.
In practice, many agents are not fully free roaming. They run inside guardrails and may be allowed to search the web, read files, write code, call business apps, or send a message, but only within clear limits. That is often a feature, not a flaw, because useful automation usually needs control.
An AI agent is not just a model. It is a model plus a loop that lets it act, observe, and try again. In practice, useful agent designs balance autonomy and constraints so they complete tasks without drifting into risky or irrelevant actions.
Why AI Agents Feel Different From A Normal Chatbot
A normal chatbot usually works in one shot. You type a prompt and the model predicts the next words, returning one response. If the answer is wrong, incomplete, or missing data, the burden falls back on you to ask again.
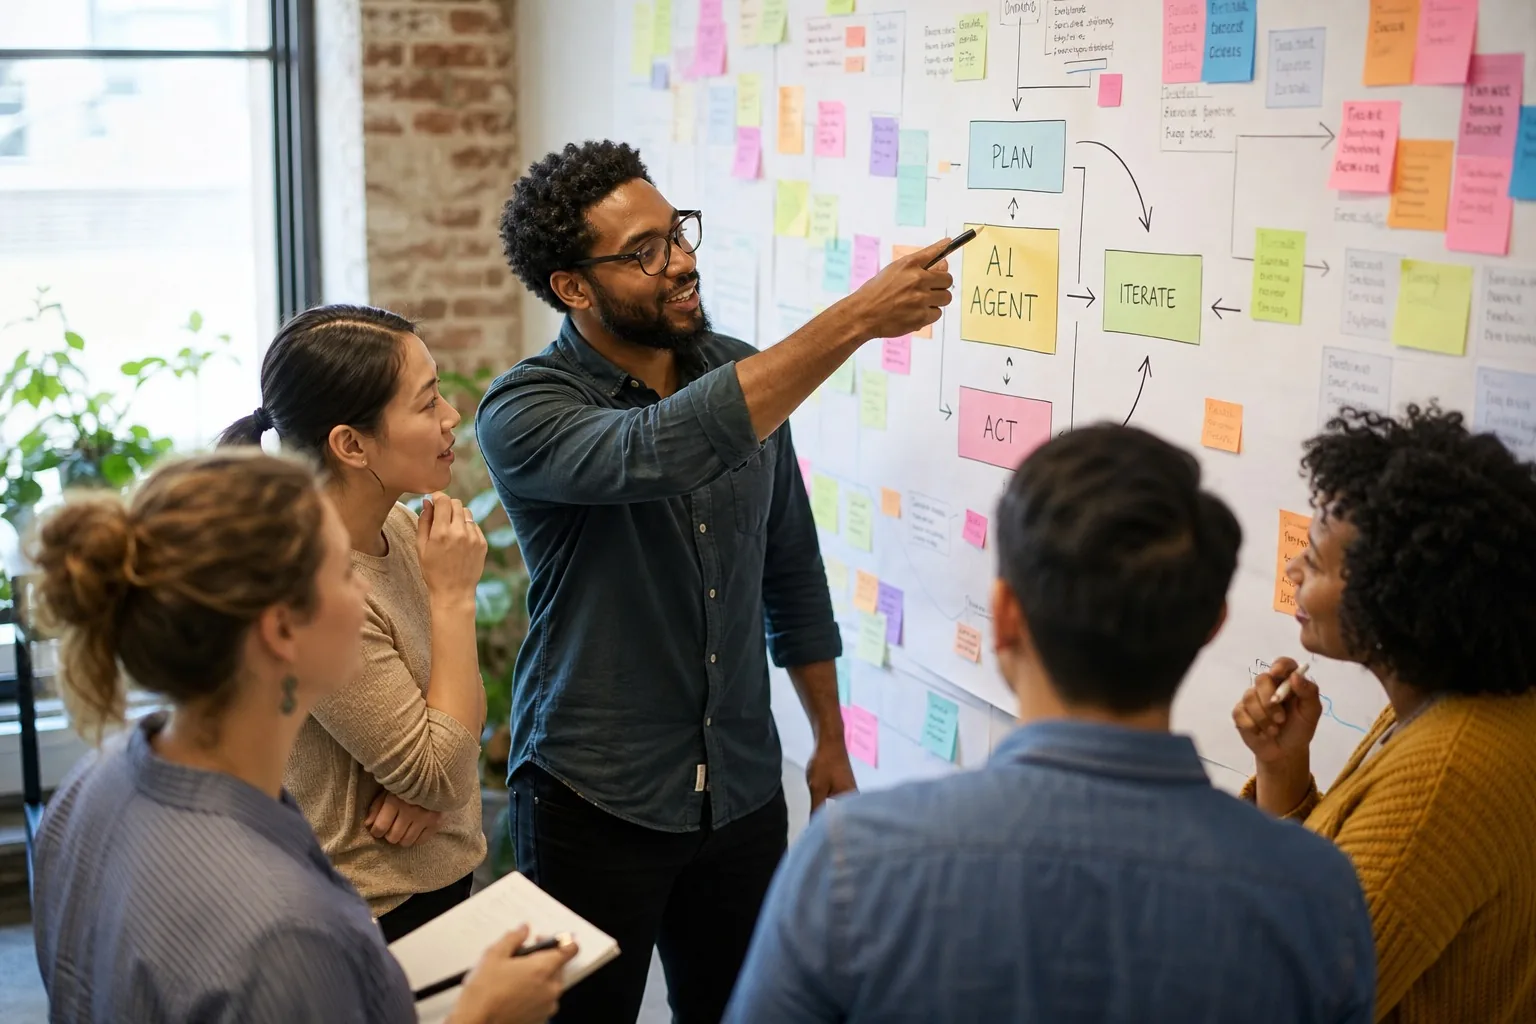
Agents change that pattern by running a loop that can understand the goal, make a plan, choose a tool, take an action, inspect the result, adjust the plan, and repeat until done or stopped. That loop is the real gap between AI agents and standard chatbots. It gives the system a way to interact with the world instead of only describing it.
OpenAI said agents fit best where a task needs judgment calls, where the rules are too messy to keep up to date by hand, or where the work means reading lots of unstructured documents and emails. If every step is predictable, a plain workflow or standard software rule may work better.
For example, imagine you ask for “a list of the cheapest flights to Chicago next month.” A chatbot might suggest websites to check. An agent could open search tools, compare dates, filter by price, and return a short table.
If you then ask it to book, it may need another tool, another check, and another decision. Each step depends on what happened in the last one, which is also why agent systems often look less magical in real life than in demos. The more steps they take, the more chances they have to choose the wrong tool, misread a result, or drift away from the goal.
The Four Building Blocks Behind AI Agents
Most useful AI agents rely on four core pieces. New products may package them in different ways, but the pattern stays similar.
Planning
Planning means deciding what to do first, second, and third. The model turns a goal into smaller tasks. That can be as simple as making a checklist, or it can involve picking between strategies.
Without planning, an agent behaves like a very talkative autocomplete system. With planning, it can work through a messy task in order. The plan may be written out, hidden in the system logic, or updated during the run.
Memory
Memory lets the agent keep track of what matters. This can mean short-term memory, like the last few steps in a task, or long-term memory, like saved preferences, prior files, or earlier outcomes.
Short-term memory helps the agent avoid repeating itself and long-term memory helps it act consistently over time, but memory can also create problems. Bad memory can make the agent cling to old errors or expose private data if it is not handled carefully.
Tools
Tools are what let an agent do things instead of only talk about them. A tool can be a search function, a code runner, a spreadsheet app, a customer support system, a map, or a web browser.
The model decides when to call a tool and what input to send.
Feedback
Feedback closes the loop. After each action, the agent needs to know what happened. Did the code run? Did the search return useful results? Did the email fail? The answer becomes the input for the next step.
Planning gives direction. Memory keeps context. Tools create action. Feedback lets the agent correct itself.
These four parts explain why agents are harder to build than chatbots. A one-shot model only has to respond. An agent has to respond, act, track, and recover.
How AI Agents Use LLMs And Tools That Connect Them To Their Surroundings
The language model, or LLM, is the main part of many agent systems. LLM means large language model, a kind of AI trained to predict and generate text. By itself, an LLM can summarize, write, classify, and answer questions. Inside an agent, it becomes the decision engine.
The environment interface is the other half, the bridge between the model and the world around it that tells the agent what actions are possible and what information comes back after each action. In simple terms, the interface is how the model reaches outside the chat box.
That interface might include a browser for web pages, a file system for documents, a code tool for scripts, an app connector for calendars or email, a search tool for databases, or a human approval step for risky actions.
OpenAI said useful agents need a harness that keeps track of context, uses tools efficiently and coordinates helper agents, and that it now runs and updates that harness alongside its models. That matters because many failures come from the system around the model, not just from the model itself.
A simple way to think about it is that the LLM decides, the interface executes, the environment responds, and the agent updates and tries again. This helps explain why agents are not a separate species of AI. They are usually systems built around an LLM, not a complete replacement for one.
Also Read: Claude Polices Its Own Chats And Caught 100,000 Child Abuse Items From One Client
Why Multi-Step Agents Can Be Powerful And Fragile
Agents shine when work has many moving parts. Research, coding, customer support triage, data entry, and travel planning all fit this shape. A one-shot answer is often not enough. The task needs searching, checking, revising, and finishing.
OpenAI said its deep research system is designed to synthesize large amounts of online information and complete multi-step research tasks. That is a classic agent pattern. The system does not just answer from memory. It explores, collects, evaluates, and then writes.
The strength is obvious. Agents can handle work that would otherwise mean five or ten separate prompts and can reduce the “prompt babysitting” that normal chatbot use often needs. But the weakness is just as real, every extra step adds risk. Here are the main trade-offs.
- More failure points: A tool can time out. A search result can be bad. A model can misread output.
- Higher cost: More steps usually mean more model calls and more tool usage.
- More delay: A one-shot answer may take seconds. A multi-step agent may take much longer.
- Harder testing: It is easier to test a fixed prompt than a system with branching paths.
- Safety concerns: Agents with access to email, files, or payments need tighter controls.
The same loop that makes agents useful also makes them brittle. They get more done by taking more steps, and more steps create more places to fail. This is why many companies prefer narrow agents over general ones. A billing agent that reads invoices and fills forms is easier to trust than an open-ended “do anything” assistant. The smaller the action space, the easier it is to predict behavior.
Single-Agent And Multi-Agent Systems Are Not The Same
Not every agent works alone. Some systems split work across several agents, where one main agent may assign jobs to specialist agents for coding, search, or review. That can help on broad tasks, but it also adds coordination problems.
A single-agent system is easier to reason about. It has one memory, one planner, and one action loop. A multi-agent system can cover more ground, but it may duplicate work or lose track of the main goal if the handoffs are weak.
You can think of it like a solo freelancer versus a small team. The team can do more, but it also needs project management. That is why many real systems start with one agent and only add subagents when there is a clear reason.
Researchers have also tried more open-ended agent designs for years. Projects like Auto-GPT and BabyAGI made the idea popular with hobbyists, but they also showed a common problem. Agents that can do many things often spend too many steps wandering, repeating, or chasing weak goals.
That does not mean the idea failed. It means the hard part was never “make the model talk to tools.” The hard part is “make the system stay useful, efficient, and correct over time.”
Who Should Use AI Agents And Who Should Not
AI agents are appealing because they promise less manual work, but they are not the right answer for every person or every company. Often, a normal chatbot, a saved prompt, or plain automation is enough.
Agents make the most sense when the task takes many steps, the next step depends on the last result, the job needs tool use, rules change often, or human workers already spend time stitching apps together.
Examples include research assistants that gather and organize sources, coding helpers that write, test, and fix code, support agents that route tickets and draft replies, and operations tools that move data between systems.
Agents make less sense when the task is one clean question, accuracy must be near perfect every time, the process is fixed and simple, the action is high risk (like sending money or legal approval), or the cost of a mistake is higher than the labor saved.
For a student or beginner, the best way to think about it is practical. If you keep needing three or four follow-up prompts to finish the same task, an agent may help. If one good prompt already solves it, an agent may only add complexity.
OpenAI said coding agents are speeding up experiments inside its own research teams and taking on bigger tasks, which is a good clue about where agents fit best. They do well where there is repetition, branching work, and a clear way to test progress.
The safest path for most users is “human in the loop,” where the agent can prepare work but a person approves key actions. This setup keeps much of the speed benefit without handing over full control.
Conclusion
AI agents are best understood as systems, not just models. The model provides language and reasoning, but the agent adds planning, memory, tools, and feedback. That combination lets it do multi-step work instead of stopping at a single answer.
The real gap between AI agents and chatbots is that a chatbot mainly responds, while an agent can respond, act, inspect, and continue. The reward is more useful automation, and the cost is more complexity, more delay, and more room for mistakes.
For newcomers, the easiest test is simple. Ask whether the job needs action or only explanation. If it needs action across several steps, an agent may help. If it just needs one solid answer, a normal model is often the better tool.
Read Next: Google Tests Gemini 4 Carbon In Secret To See If People Like It