Nvidia Gives Banks And Hospitals More Control Over AI Transcripts
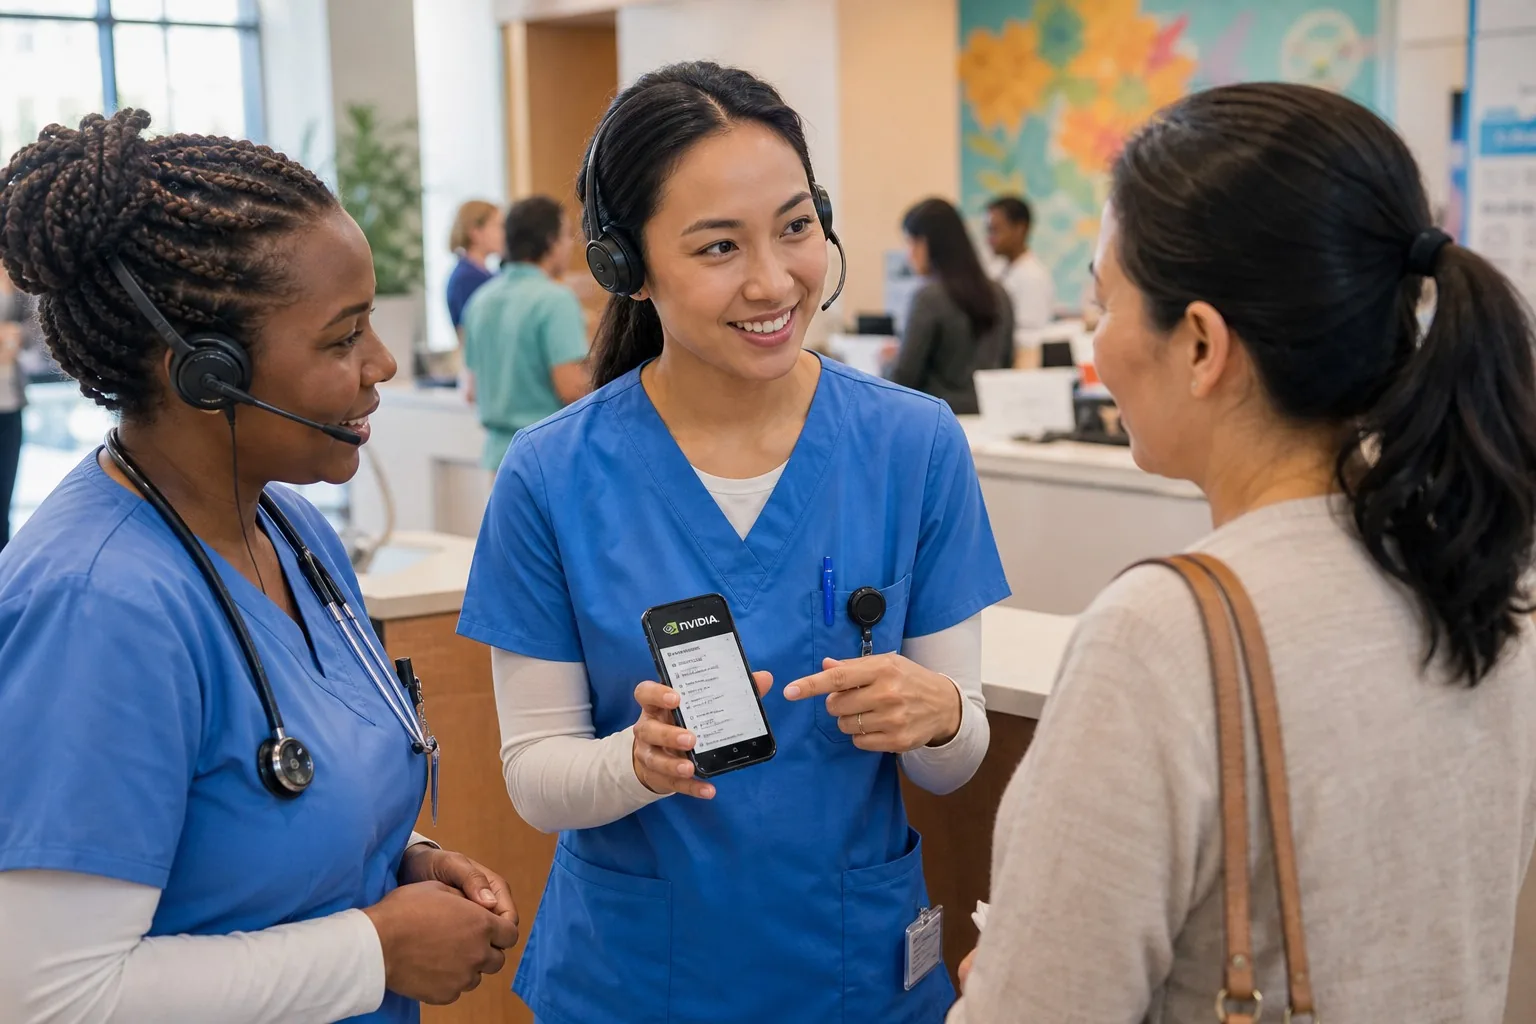
Nvidia has released Nemotron Transcribe 3.5, a speech to text tool, and Granary, software that shapes transcripts for company systems, giving banks and hospitals more control over how recorded calls and notes are written up.
Key Takeaways
- Nvidia posted Nemotron Transcribe 3.5 and Granary v2 on its Hugging Face channel within the hour
- Nemotron 3.5 supports promptable transcription so users can steer output with instructions, vocabulary or formatting rules
- Granary v2 broadens the pitch from pure transcription toward adaptation for downstream structured outputs
- Nvidia also promoted local AI tools on new RTX Spark laptops in a separate company post
Nvidia posted the release through its official Hugging Face channel within the hour. The company sells the GPUs behind much of the AI market, but it also publishes models and software meant to keep developers inside its stack from training through deployment.
A separate Nvidia post on Wednesday showed the company also pushing local AI tools onto new RTX Spark laptops.
Nemotron Transcribe 3.5 Targets Promptable Speech Work
Traditional automatic speech recognition tries to turn audio into text with as little user control as possible. That works for generic dictation, but it breaks down in medicine, law, support logs and multilingual meetings.
Nemotron 3.5 takes a different approach.
Promptable transcription means the user can steer the model with instructions, vocabulary or formatting rules. If a hospital wants medication names preserved, or a newsroom wants speaker labels and timestamps in a certain format, the model can be guided toward that output.
Granary v2 broadens the pitch from pure transcription toward adaptation.
That matters because enterprises often need more than a raw transcript. They need a transcript shaped for the system that consumes it next.
Nvidia Keeps Climbing Up The AI Stack
This release fits a larger pattern.
Nvidia no longer acts only as the chip supplier. It is building reference models, domain libraries and deployment tooling that make its hardware harder to leave.
That strategy matters in speech because the market is crowded.
Open-source speech models, cloud APIs and startup tools already cover basic transcription well. Nvidia needs a reason for developers to switch, and control is one answer.
If transcription can be tuned through prompts instead of a full fine-tune, teams can adapt faster and spend less time rebuilding pipelines.
Also Read: Invesco Hands Advisers 2 Claude Tools To Build Portfolios Faster
The company has pushed a similar message across coding, agents and local AI. Sell the hardware first, then keep the workflow anchored to Nvidia software.
The capital spending visible in Nvidia’s product moves, persistent investment in GPUs and local deployment channels, indicates the company will prioritize solutions like Nemotron Transcribe that favor heavy, on-prem and CUDA-optimized inference over lightweight alternatives.
When a firm’s public strategy touts openness but its hardware spending keeps capacity, supply and power-hungry inference in mind, the spending is the more reliable signal of where production workloads will end up.
How Nemotron 3.5 Could Reshape Speech Pipelines
Nemotron 3.5 matters most to teams that treat speech recognition as infrastructure, not a demo. A bank recording support calls, a health system processing clinician notes and a media firm transcribing interviews all care about the same thing.
The transcript has to fit a downstream workflow.
That is where promptable transcription changes the job. Instead of retraining a model or writing a brittle cleanup script after every transcript, developers can instruct Nemotron 3.5 at inference time.
Granary v2 appears aimed at that layer between raw audio and structured business output.
Analysis must weigh real constraints. Capacity, supply, power and cost per unit of inference will determine whether Nemotron Transcribe is practical at scale.
High-capacity enterprise deployments will favor models that exploit ample GPU supply and tolerate increased power draw if the per-inference cost falls compared with expensive human transcription or complex fine-tuning cycles.
Conversely, organizations constrained by limited GPU availability or tight operational budgets may prefer lighter cloud APIs or edge-optimized models. Nvidia’s ongoing capital commitments to GPU capacity and software integration signal the company expects customers to accept the power and supply profile required to run Nemotron Transcribe in production.
When capital spending and public strategy diverge, the capital spend is the better predictor of long-term direction.
Compared with older speech systems, that shifts effort from model customization toward runtime control. Nvidia benefits if developers see that as the easier path and keep the workload inside CUDA-heavy environments.
The next thing to watch is benchmark disclosure. If Nvidia publishes word error rates, latency and language coverage against Whisper-class rivals, buyers will have a clearer reason to test it.
Read Next: Oracle Hands Google AI Chips To Cloud Buyers Eyeing Nvidia